eBPF network insight
Some things /proc can’t show: TCP retransmits, resets and round-trip times per workload, the DNS names an app asks for and how often they fail, or how long a workload waits for a CPU. Since v0.18.0 a small eBPF probe can measure them. It is off by default, turned on per server by an admin, and only reads.
Turn it on
Section titled “Turn it on”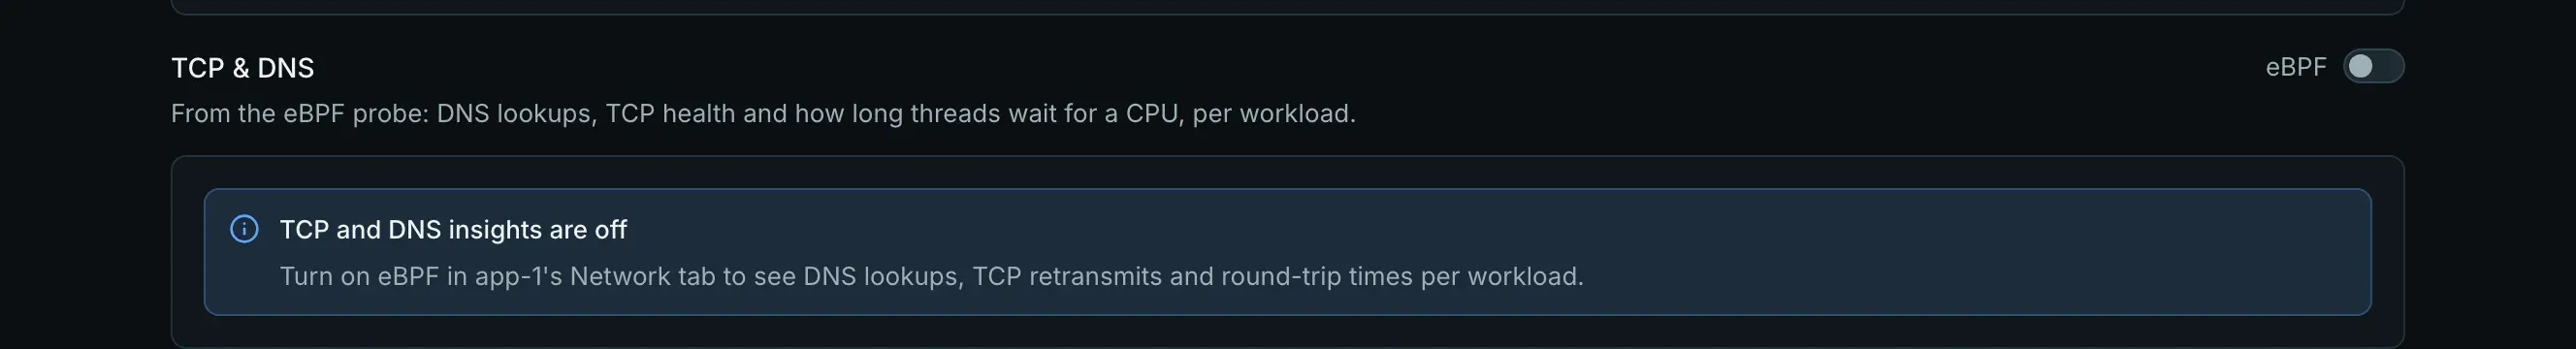
- Open the server page → Network.
- Switch on eBPF (needs
network.ebpf, admins only;network.manageis not enough). The change is audited. - Optionally switch on Full DNS names (below).
The card shows the probe’s state from the agent: Not supported with the reason, Running (with its CPU overhead), Running in part, Turned off: over its CPU budget, or The probe did not start with the error. The setting is sent again until the agent has applied it, also when the agent was offline or is upgraded.
Requirements
Section titled “Requirements”- Linux 5.8 or later on amd64 or arm64, with BTF (
/sys/kernel/btf/vmlinux) and cgroup v2. Ubuntu 22.04 and later have them. - The agent must be allowed the
bpf()syscall (not an unprivileged container). - Agent feature
net.ebpf(v0.18.0).
What you see
Section titled “What you see”A TCP & DNS section below the connections on the server, site and database Network tabs:
| Area | Charts |
|---|---|
| DNS | Queries per second, failures by error (NXDOMAIN, SERVFAIL, REFUSED, other, timeout), latency p50 / p95, the top names with their failures |
| TCP | Retransmits by peer, resets sent and received, RTT p50 / p95, connect latency p95, failed connects |
| Run queue | How long processes waited for a CPU: p50 / p95 / p99 |
| Probe overhead | The probe’s own CPU cost (server tab) |
Peers are named like the rest of the Network tab (your servers, databases and sites; other addresses as public, private or local buckets). No IP address is ever a metric label.
DNS names are folded to their registrable domain by default (api.eu.stripe.com → stripe.com). Full DNS names ships them whole. Each workload keeps its top 10 names (ranked over about an hour), stored 30 days like every metric. On the server’s tab, the names asked by processes outside every site are shown only to members with network.manage.
What it doesn’t see
Section titled “What it doesn’t see”- DNS over TCP, DNS over TLS and DNS over HTTPS (UDP port 53 only). Through systemd-resolved a lookup counts twice: the app’s query and the resolver’s upstream one.
- Native sites sharing the
falakuser: their DNS counts for the server. Inbound TCP of native sites is the edge’s (Caddy talks to PHP-FPM over a unix socket); their outbound connections are theirs. - An entry evicted from the probe’s bounded maps loses what it counted since the last read: the probe can under-count, never double-count.
Safety and cost
Section titled “Safety and cost”- Read-only: no program changes, drops or redirects a packet.
- Tied to the agent: the kernel removes the probe when the agent stops or crashes. Any load error leaves the agent running and the card says what failed.
- Budget: the probe measures its own CPU and stays under 1 % of the machine’s capacity. Above it, it first sheds the run-queue programs (the most expensive part), then switches itself off. The stop survives agent restarts and upgrades: only an admin’s Re-enable, or turning the setting off, clears it.
- While the probe runs, the kernel’s BPF run-time statistics are on for the whole host, which adds a few tens of nanoseconds to every BPF program run on it.
Alerts
Section titled “Alerts”Two alerts join the Network area of the default rule pack, evaluated every minute per workload over 5 minutes:
| Type | When |
|---|---|
network.dns_failures |
At least 60 answers with an error other than NXDOMAIN, and at least 20 % of the queries, held 5 minutes |
network.tcp_retransmits |
At least 3,000 retransmits for a site or database (6,000 for the server’s own processes), held 5 minutes |
NXDOMAIN and unanswered queries are left out of the failure alert: search domains make NXDOMAIN common and harmless.
Metrics
Section titled “Metrics”falak_net_tcp_retransmits_total, falak_net_tcp_resets_total, falak_net_tcp_connects_total, falak_net_tcp_peer_rtt_seconds, falak_net_tcp_connect_duration_seconds, falak_net_tcp_rtt_seconds, falak_net_dns_queries_total, falak_net_dns_failures_total, falak_net_dns_duration_seconds, falak_net_dns_name_queries_total, falak_workload_runqueue_delay_seconds, and falak_ebpf_cpu_time_seconds_total / falak_ebpf_active for the probe itself. Histograms are stored as _bucket, _sum and _count.